Why widespread disruption demands more than conventional recovery planning
The government’s new “Be Ready” campaign comes with a direct challenge for business leaders. Defence Secretary Wes Streeting says businesses, as well as the public, need to think harder about how they would cope with natural disasters, cyber-attacks and state-sponsored terrorism. For households, the advice is practical: keep enough food, water and essential supplies to manage for three days. For businesses, the implications are more demanding.
A conventional business continuity plan usually assumes that the incident happens to one organisation at a time. A fire damages your premises, a cyber incident takes down your systems or a supplier fails. The recovery strategy then relies on the wider system remaining available: employees can travel or work elsewhere, alternative suppliers can operate, customers can be contacted, and energy, transport, banking, communications and cloud services continue to function.
But would that plan still work if the disruption did not stop at the edge of the business? What happens when the utilities, people, suppliers and digital services on which recovery depends are also affected across an entire region or market? The kind of event contemplated by “Be Ready” may remove several recovery assumptions at once.
A different question for business leaders
Preparedness therefore cannot stop at asking whether the office has torches, bottled water or a battery radio. The traditional continuity question is: How do we keep delivering while our organisation is disrupted? During systemic disruption, the better question may be: How do we protect our people, preserve control and prepare to restart when the wider system recovers?
Three functions, but a different balance
A practical continuity plan normally contains three connected functions:
-
Emergency response - This is the immediate work of detecting the incident, protecting life, containing harm and escalating when the situation can no longer be managed locally. During systemic disruption, this becomes especially important. Organisations may need to account for staff without normal communications, make sites safe, secure data and stock, conserve fuel and other scarce resources, and decide when continued operation is unsafe.
-
Crisis management - The crisis team assesses the changing impact, sets priorities, directs the response and communicates with employees, customers, regulators and other stakeholders. In a widespread incident, leaders may have incomplete information and unreliable communications. Authority therefore needs to be delegated in advance, and decisions should be possible without waiting for every member of the usual team.
-
Operational recovery - For an isolated incident, operational recovery often dominates: relocate work, invoke alternative suppliers, restore systems and prioritise critical customers. In a systemic incident, many of those options may be unavailable. Recovery can become less about sustaining normal output during the disruption and more about limiting irreversible damage and preparing for an orderly restart.
All three functions still matter, but their relative weight changes. Emergency response and crisis management move to the foreground. Conventional recovery may remain constrained until infrastructure, people and the wider market begin to return.
When everyone is affected, tolerances change
A market-wide event also challenges the assumptions behind the business impact analysis. If one manufacturer stops while competitors continue, customers may switch quickly. If the entire sector is disrupted, their expectations and tolerance may change. Demand may fall, contracts may be interpreted differently, regulators may adjust priorities and customers may accept altered service levels because the constraint is shared.
This is a strong case for testing systemic disruption separately rather than adding it as one more scenario in an otherwise conventional plan. A market-wide impact assessment should examine how demand, obligations, competitive pressure and acceptable downtime change when the surrounding economy is impaired.
Plan for dependencies, not just hazards
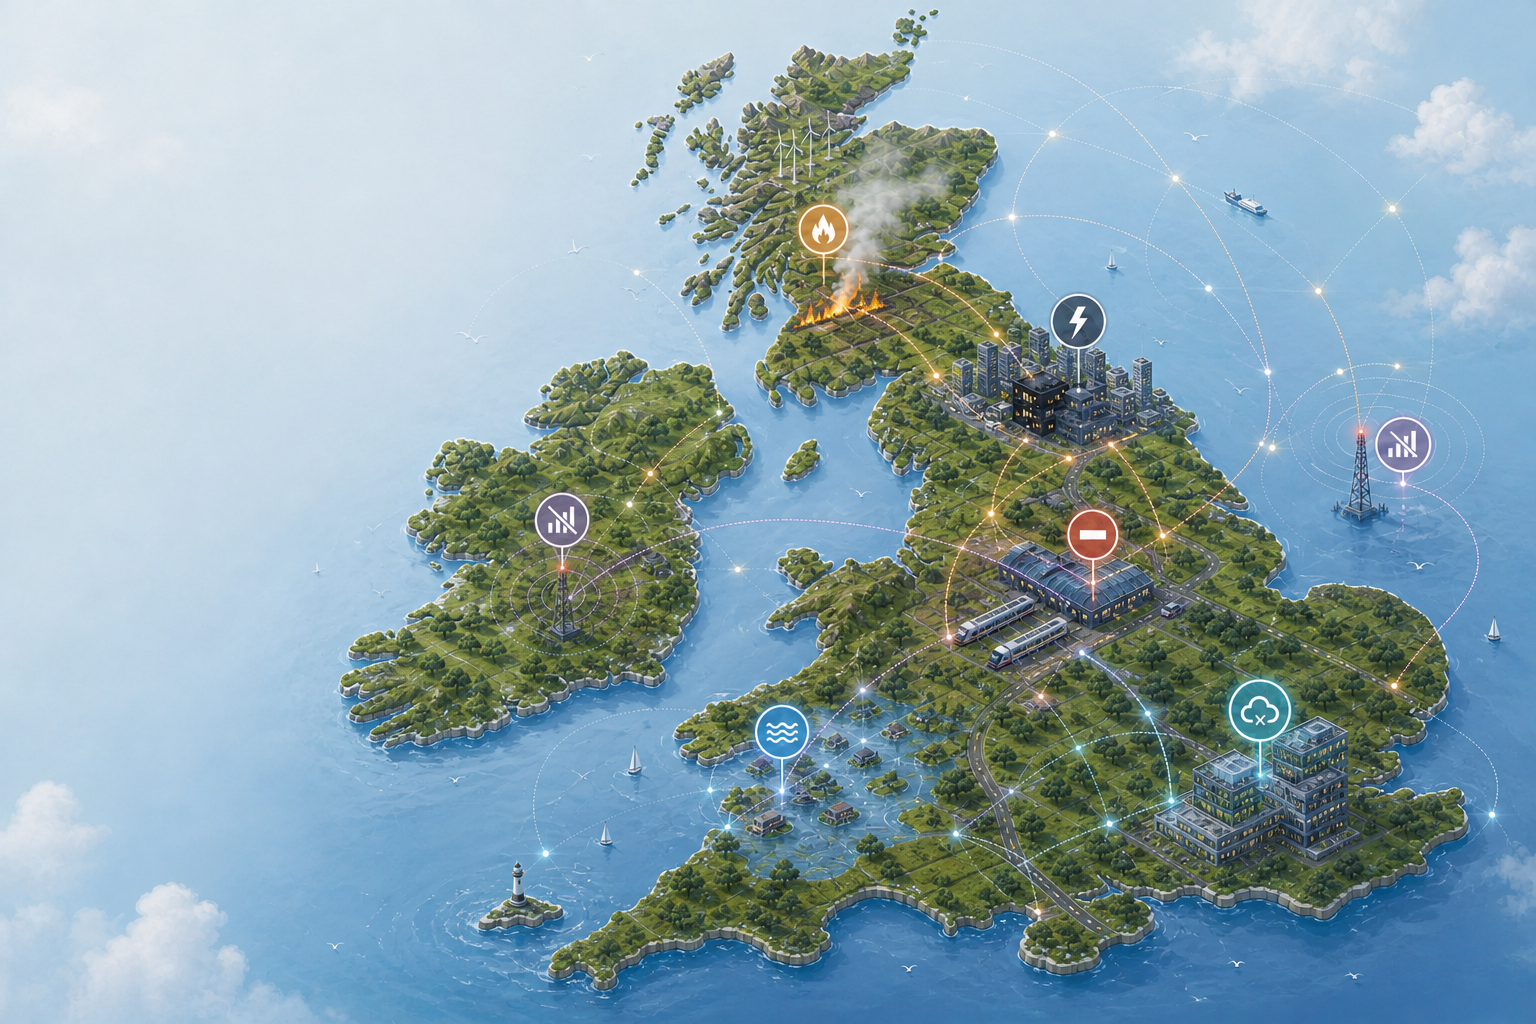
The most useful scenarios are not simply a list of dramatic events. They describe what might happen, how widely it might spread and which shared dependencies could fail as a result. Organisations should consider, for example:
- gas shortages that constrain electricity generation;
- prolonged or regional electricity outages;
- loss of mobile, internet and other communications;
- regional flooding, wildfire, drought or other extreme weather;
- transport and fuel-distribution disruption; and
- major failures affecting cloud or digital service providers.
Each scenario needs realistic assumptions about its severity, duration and geographic reach. An outage lasting an hour creates a different problem from one lasting a day, a week or a month. A local communications failure may be manageable; a regional failure could leave employees, customers and suppliers unable to contact one another.
Scenarios should also account for knock-on effects. A power cut, for example, may also disrupt mobile networks, card payments, fuel supplies and transport. Staff may be unable to travel or contact the business, while suppliers and repair services face the same problems. The real challenge may be not the initial event, but the chain of consequences that follows.
From recovery plans to preparedness
No organisation can build a complete workaround for every systemic shock. It can, however, reduce avoidable harm and increase its readiness to restart. Useful preparations include:
- methods for accounting for staff when mobile and internet services are unavailable;
- clear delegated authority when senior leaders cannot be reached;
- criteria for suspending operations for safety or commercial reasons;
- manual or offline procedures for essential decisions and transactions;
- plans to secure premises, critical data, stock and cash;
- an understanding of which suppliers share the same infrastructure dependencies;
- priorities for conserving backup power, fuel and other scarce resources;
- controlled shutdown and restart procedures for critical equipment and systems; and
- a defined minimum service that can be delivered without normal utilities or cloud platforms.
These preparations should be supported by short, usable playbooks rather than an elaborate plan for every imaginable event. The goal is to establish the assumptions, triggers, responsibilities and immediate actions that remain credible when normal support is unavailable.
The real measure of resilience
In a widespread incident, continuing as normal may be impossible. It may not even be necessary if customers, competitors and the rest of the market have also stopped. Trying to preserve output at any cost can distract from more important priorities: keeping people safe, retaining command of the situation, preventing avoidable damage and protecting the organisation’s ability to return.
The decisive advantage may come after the outage. Businesses that know how to assess damage, contact their people, restart equipment, restore critical information and sequence operations will be able to move faster as infrastructure returns. Those that have treated resilience only as a set of recovery workarounds may discover that those workarounds disappeared at the same moment they were needed.
Systemic disruption does not make business continuity planning irrelevant. It exposes where its assumptions end. The organisations best prepared will not be those claiming they can operate indefinitely while the country around them has stopped. They will be those able to protect life, preserve control and come out of the blocks quickly when the lights come back on.